
Overview
Six months ago, your team decided to automate testing. Someone picked a framework, the QA engineers started converting manual test cases into scripts, and for a while the dashboard looked great. Today, a third of the suite fails on any given run. Nobody is sure which failures are real. Before each release, the team quietly runs the important checks by hand, just to be safe.
That's what test automation looks like without a strategy. A test automation strategy is the plan that decides what you automate, at which level, with which tools, who owns the tests, and how you'll know the effort is paying off. It turns automated tests from a pile of scripts into something the team actually relies on.
In this guide, we'll cover how to decide which tests to automate, the key components of a strategy, a seven-step way to build one, and how to estimate whether it will pay off. You'll also find a test automation strategy document template with a filled-in example you can adapt for your own project.
What Is a Test Automation Strategy?
A test automation strategy is a document that sets out why and how a team automates testing: the goals, what's in and out of scope, which levels and types of tests get automated, the tools and test automation framework, how test data and environments are handled, how tests run in the CI/CD pipeline, who owns them, and which numbers show whether it's working.
Test automation itself is simply using software to run checks that would otherwise be done by hand. The strategy is what keeps that automation pointed at the right problems. Without it, teams tend to automate whatever is easiest to script, which is rarely what matters most to the business.
You need one if your product ships regularly, will be maintained for years, or already has automated tests that don't deliver much value. A two-week prototype doesn't need a strategy document. A platform your company will run for the next five years does.
Test Automation Strategy vs. Test Strategy vs. Test Plan
These three terms get mixed up constantly, and the confusion leads to documents that try to do everything and end up doing nothing well.
| Document | What it answers | Lifespan |
|---|---|---|
| Test strategy | How the organization or product approaches quality overall: levels of testing, manual and automated, risk approach, standards | Long-term, changes rarely |
| Test automation strategy | The automation part of that: what to automate, how, with what, who owns it, how success is measured | Long-term, reviewed regularly |
| Test plan | What gets tested in a specific release or project, when, by whom, with which resources | Short-term, one per release or project |
In short, the test strategy sets direction, the test automation strategy turns part of it into an engineering practice, and the test plan schedules the work. For more on how quality is ensured at each stage, see our guide to levels of software testing.
What Goes Wrong Without an Automated Testing Strategy
A test automation project rarely fails in one dramatic moment. It drifts, usually in the same stages.
It starts with the wrong tests. Without agreed priorities, people automate what's easy: login, static pages, forms with two fields. Those tests pass every day and prove very little. Meanwhile, the billing logic that breaks twice a quarter is still checked by hand, because scripting it looked hard. The suite grows, test coverage looks impressive in a report, and the risky parts of the product stay exposed.
Then maintenance catches up. Every UI change breaks a dozen locators. Fixing them takes a day here, two days there, and soon the automation engineers spend more time repairing existing tests than writing new ones.
Flaky tests do the most damage. Picture a login test that fails once in every twenty runs for no clear reason. The first few times, someone investigates. After a month, everyone just clicks "re-run." Once a team learns to ignore red builds, real failures slip through too, and the suite stops being a safety net.
Ownership blurs. When nobody is explicitly responsible for the suite, broken tests sit unfixed because "QA will handle it" or "the developer who changed the code should fix it." Both groups wait for the other.
And finally, leadership loses interest. If no one can show that automation efforts shortened regression or reduced production defects, it starts to look like a cost center. Budgets get cut, the suite decays further, and the team is back to manual testing, with a graveyard of scripts as a reminder.
An automation strategy doesn't make these problems impossible. It makes them visible early, and assigns someone to deal with each one.
The most common starting mistake is counting automated scripts instead of risk covered. A large green suite that never touches billing, permissions, or money paths is still a gap dressed up as progress.
Which Test Cases to Automate and What to Leave to Manual Testing
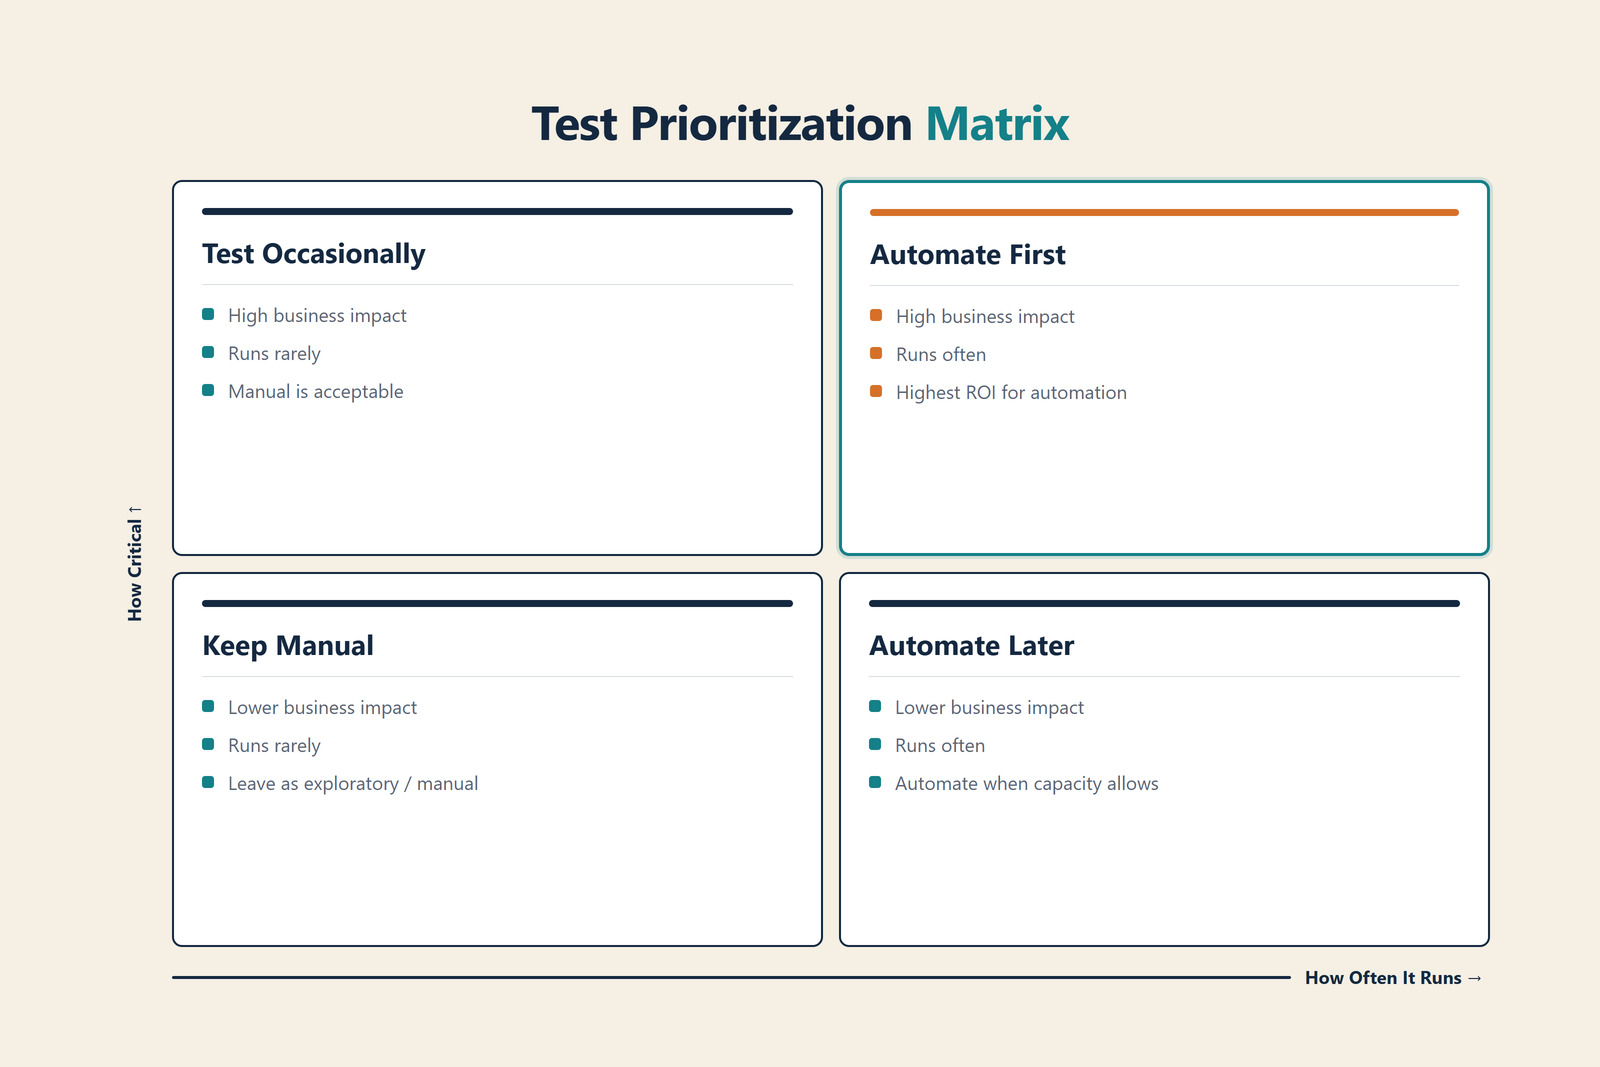
Not every test should be automated, and trying to automate everything is one of the fastest ways to sink a project. A test case is a good candidate when most of these are true:
- It runs often, for example on every build or every release.
- A failure would hurt the business: money, data, compliance, or customers who can't do their job.
- The functionality is stable and won't be redesigned next sprint.
- It needs many data combinations that are tedious to check by hand.
- It's repetitive enough that a person doing it manually is likely to miss something.
That's why regression testing and smoke tests are almost always the first to be automated. They protect existing functionality, they run constantly, and they are exactly the kind of work people find mind-numbing.
Manual testing still has a place, and not as a fallback. Manual and exploratory testing, where a tester actively hunts for unexpected behavior, depends on human judgment and curiosity. Usability testing needs a person to notice that a flow is confusing even though it technically works. Accessibility checks can be partly automated, but a human still needs to try the product with a screen reader. Features in active redesign aren't worth scripting yet, and scenarios that run once a year rarely justify the maintenance cost.
For a B2B accounting SaaS, prioritization might look like this:
| Priority | Area | Why |
|---|---|---|
| Automate first | Invoice calculation, tax rules, payment export to banks | Business-critical, many data combinations, runs every release |
| Automate next | User roles and permissions, report generation | Important, stable, regularly affected by other changes |
| Automate later | Settings pages, notification preferences | Lower risk, changes less often |
| Keep manual | New onboarding flow in redesign, usability of dashboards | Unstable or needs human judgment |
The Test Pyramid: Getting Test Coverage at the Right Level
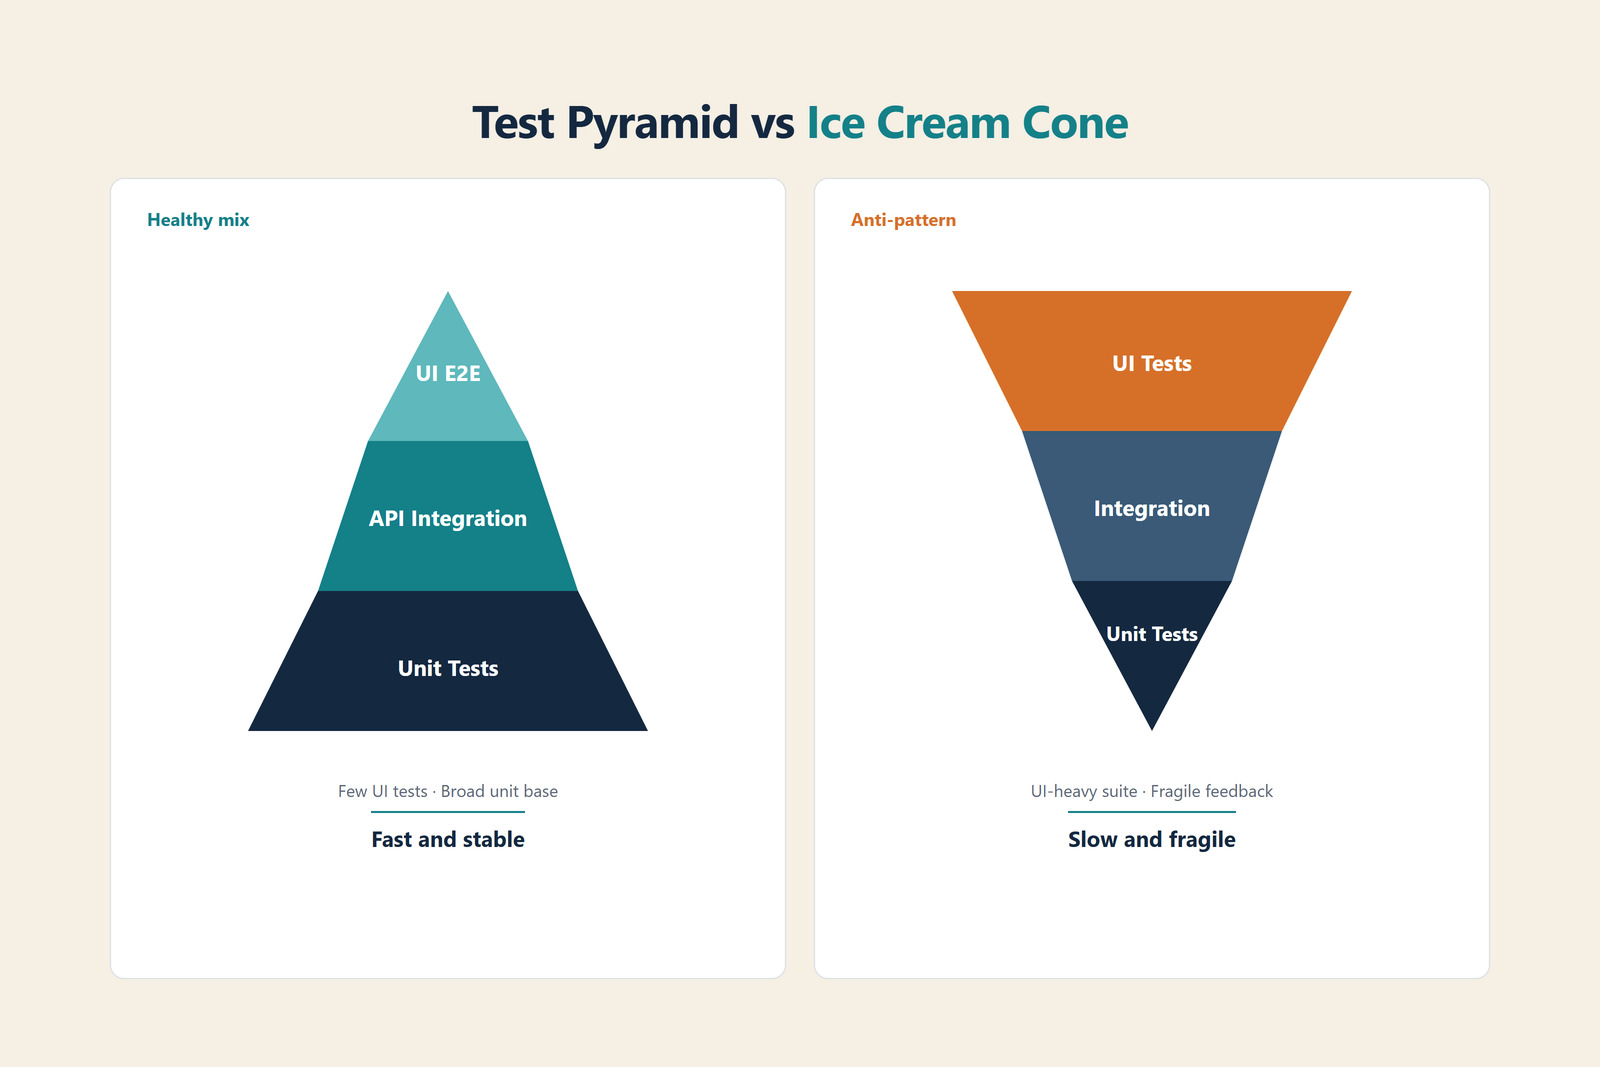
Deciding what to test is half the question. The other half is at which level. The test pyramid is still the most useful model here: a wide base of fast unit tests, a middle layer of integration tests and API tests, and a thin top layer of end-to-end UI tests.
The logic is about cost and speed. Unit tests run in milliseconds and pinpoint the broken function. UI tests take minutes, break when a button moves, and when they fail, you still have to figure out why. If a rule can be checked at the API level, checking it through the browser just adds time and fragility.
Many teams end up with the opposite shape, often called the ice cream cone: lots of slow UI tests, a few integration tests, and almost no unit tests. It usually happens when manual testers convert their test cases one-to-one into browser scripts. The suite takes hours, breaks constantly, and still misses logic errors that a unit test would catch in seconds.
Where Performance Testing Fits
Performance testing can and should be automated, but it lives on its own schedule. Load tests need a production-like environment, take time to run, and produce results that someone has to interpret against a baseline. How often to run them depends on your traffic profile, the cost of the environment, and how often performance-critical parts of the system change: for some teams that means nightly, for others weekly or before major releases. What almost nobody needs is a full load test on every commit. Tools such as k6 or Apache JMeter are common choices, and the scenarios should come from real usage data rather than guesses.
Key Components of a Robust Test Automation Strategy
Whatever format you use, a robust test automation strategy answers the same set of questions. What should automation achieve, in numbers? ("Cut regression from three days to four hours" is a goal; "improve software quality" isn't.) What's in the test scope, and what's explicitly out? How is the effort split across unit, API, UI, performance, and security tests, and how are priorities set? Which tools and framework will you use, and how are test data and environments handled? What runs on each commit, before deployment, and on a schedule, and which failures block a release? Who writes, reviews, and fixes the tests? What won't automation catch, and when does the strategy itself get reviewed?
For a large organization with several products, an enterprise test automation strategy adds one more layer: shared standards, shared tooling, and reusable components across teams, so that each product team isn't reinventing its own framework.
In the template below, each of these components becomes a section of the strategy document.
How to Build a Test Automation Strategy in 7 Steps
There's no single correct sequence, but this is the order that tends to save the most rework. Each step feeds the next.
1. Audit What You Have
Before planning anything, look at the current testing process honestly. How long does a full regression take? Which tests already exist, and how many of them actually pass reliably? Where do production bugs come from, and at what stage could they have been caught? Ten minutes with your bug tracker usually tells you more about where automation is needed than a week of planning meetings.
2. Set Three or Four Measurable Goals
Tie goals to things the business cares about: release frequency, time spent on regression, defects that escape to production, time from commit to feedback. Keep the list short. A strategy with twelve goals has none. Write each one as a number with a deadline, so you can measure success instead of arguing about it.
3. Define Scope and Priorities
Use the criteria from the previous section to decide what goes into automation first, and write down what stays manual. Prioritize critical tests by risk: what breaks most often, and what costs the most when it does. This is also the point to involve product owners and business analysts. They know which flows the business can't afford to lose, and they'll be your allies when you need to defend the budget later.
4. Choose Automation Tools for Your Stack and Your Team
Pick tools that match your application and the people who will maintain the tests, not whatever tops this year's rankings. If your developers write TypeScript, a framework in the same language means they can help maintain the suite. If you test a desktop app, half the popular web tools are irrelevant.
Low-code tools can bring more people into test creation, which helps when your QA team has few programmers. The trade-off is less flexibility in complex scenarios, and sometimes a harder exit if you outgrow the tool. Before committing to any of these automated testing tools, run a short pilot on a few real scenarios from your product.
| Task | Common open-source options | When it fits |
|---|---|---|
| Web UI, cross-browser web testing | Playwright, Selenium | Playwright for modern web apps; Selenium when you need the widest language and browser support |
| Front-end component and E2E tests | Cypress, Playwright | JavaScript/TypeScript teams testing their own front end |
| Mobile apps | Appium, Espresso, XCUITest | Appium for cross-platform suites; native tools for speed on one platform |
| API tests | REST Assured, Postman/Newman, Playwright API | REST Assured for Java teams; Postman when non-developers also write checks |
| Unit tests | xUnit, JUnit, pytest, Jest | Whatever matches the codebase language |
| Performance | k6, Apache JMeter | k6 for code-first teams; JMeter for GUI-based scenario building |
5. Plan Test Data Management and Test Environments
Unreliable test data is one of the most common causes of false failures. Decide where data comes from (generated, seeded, or copied and masked from production), how personal data is protected, and how each test resets the state it changed. Keep test data separate from test logic, so the same script can run against many datasets and nobody has to edit code to change an input.
Test environments matter just as much. Define them as code where you can, keep them as close to production as you can afford, and make sure one team's test run can't corrupt another's.
6. Set Up CI/CD Integration by Test Level
Automated tests that someone has to start by hand get started less and less often. Wire them into your continuous integration and delivery (CI/CD) pipeline, but not all at once on every commit. A layered setup keeps feedback fast:
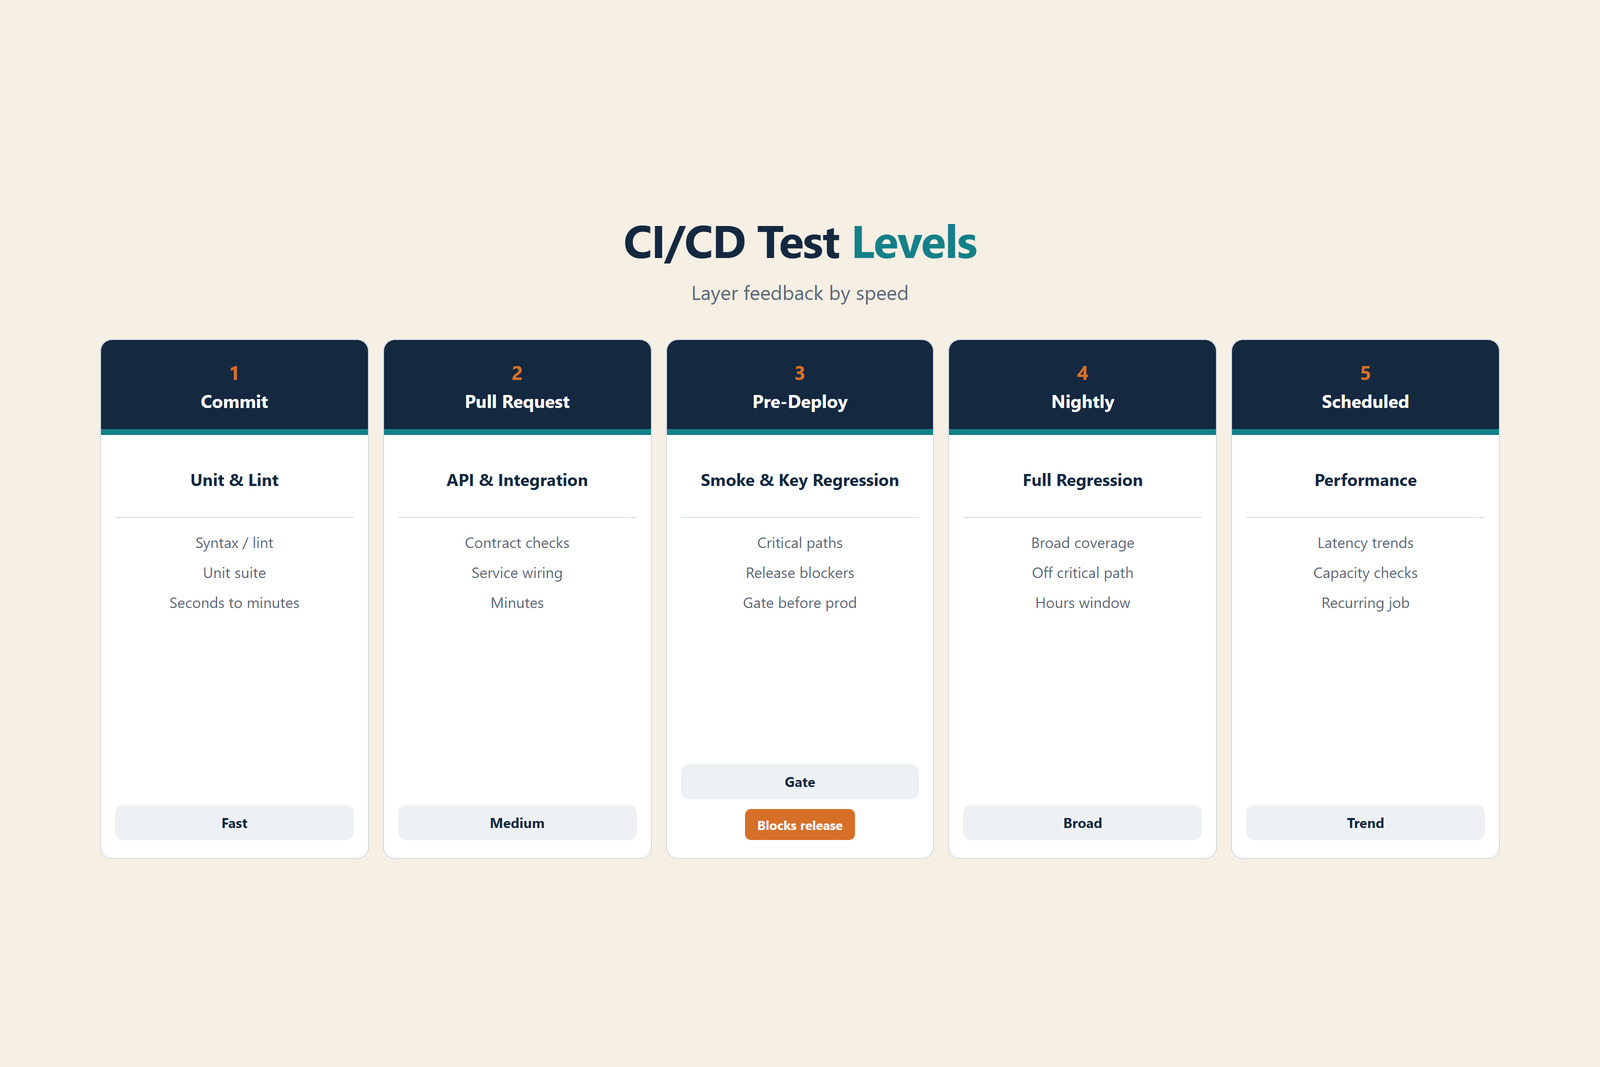
Fast unit tests run on every commit and should finish in a few minutes. Integration and API tests run on each pull request. A smoke suite and the critical regression run before deployment and block the release if they fail. The full regression and cross-browser runs go overnight, and performance testing runs on whatever schedule your load profile and budget justify. This kind of continuous testing gives developers feedback while the change is still fresh in their heads. If you're building the pipeline itself, our DevOps engineers can help, and our overview of how CI/CD works covers the basics.
7. Assign Owners and a Review Rhythm
Every test needs an owner, and every failure needs someone responsible for looking at it within a set time. Decide whether developers fix tests broken by their own changes, or whether automation engineers own the whole suite. Both models work; having no model doesn't. Teams that lack in-house capacity often bring in dedicated test automation engineers for the build-out and hand over ownership gradually.
Finally, schedule reviews of the strategy itself: after major releases, when the tech stack changes, or at least once a quarter.
Test Automation Strategy Document: Template and Worked Example
A strategy document doesn't need to be long. A few pages the team actually opens are worth more than a forty-page document nobody reads. The template below follows the components above. For each section, it shows what to write and the mistake people make most often.
| Section | What to write | Common mistake |
|---|---|---|
| 1. Purpose and goals | Why you're automating and 3 - 4 measurable targets with dates | Goals like "increase coverage" with no number or deadline |
| 2. Scope | Products, modules, platforms, and environments in scope; explicit out-of-scope list | Leaving out the out-of-scope list, so everyone assumes everything is covered |
| 3. Test levels and types | Planned split across unit, API/integration, UI, performance, security; who owns each level | Planning only UI tests because that's what manual testers know |
| 4. Prioritization | Criteria for what's automated first; the first-wave list | Choosing by ease of automation instead of risk |
| 5. Tools and framework | Tools per test type, language, framework structure, reporting | Picking tools before sections 1 - 4 are agreed |
| 6. Test data and environments | Data sources, masking, reset rules, environment list and setup | "We'll use a copy of production" with no plan for personal data |
| 7. Execution and CI/CD | What runs on commit, pull request, pre-deploy, nightly; which failures block a release | Running the whole suite on every commit until nobody waits for it |
| 8. Roles and ownership | Who writes, reviews, maintains, and triages failures | "The team" as the owner of everything |
| 9. Metrics and reporting | What's measured, where it's shown, who looks at it and how often | Measuring the number of tests instead of what they achieve |
| 10. Risks and limitations | What automation won't catch, known risks, mitigations | Skipping this section to make the plan look cleaner |
| 11. Maintenance and review | Flaky test policy, refactoring time, strategy review dates | No review date, so the document is stale within six months |
Copy-Ready Template
Copy the outline below into your wiki or document editor and fill in the brackets. Delete the lines that don't apply to your project.
TEST AUTOMATION STRATEGY: [Product / Team]
Owner: [name] Version: [x.y] Last reviewed: [date] Next review: [date]
1. PURPOSE AND GOALS
Why we automate:
- Goal 1: [metric] from [baseline] to [target] by [date]
- Goal 2: [metric] from [baseline] to [target] by [date]
- Goal 3: [metric] from [baseline] to [target] by [date]
2. SCOPE
- In scope (modules, platforms, environments):
- Out of scope:
3. TEST LEVELS AND TYPES
- Unit: owner [ ] target [ ]
- API/integration: owner [ ] target [ ]
- UI / end-to-end: owner [ ] max number of journeys [ ]
- Performance: owner [ ] schedule [ ]
- Security: owner [ ] checks [ ]
4. PRIORITIZATION
- Criteria:
- First wave:
- Second wave:
- Stays manual:
5. TOOLS AND FRAMEWORK
- Tools per test type:
- Language and framework structure:
- Reporting:
6. TEST DATA AND ENVIRONMENTS
- Data sources:
- Handling of personal data:
- Reset rules:
- Environments and how they're provisioned:
7. EXECUTION AND CI/CD
- On commit:
- On pull request:
- Before deployment (blocks release: yes/no):
- Scheduled runs:
8. ROLES AND OWNERSHIP
- Writes tests:
- Reviews tests:
- Maintains the framework:
- Triages failures, and within what time:
9. METRICS AND REPORTING
- Metrics and targets:
- Where results are shown:
- Reviewed by, how often:
10. RISKS AND LIMITATIONS
- Not covered by automation:
- Known risks and mitigations:
11. MAINTENANCE AND REVIEW
- Flaky test policy:
- Time reserved for refactoring:
- What triggers a strategy review:
Worked Example
Below is the same template filled in for an illustrative project: a B2B SaaS invoicing platform with a web app and a public API, a team of six developers and two QA engineers, and releases every two weeks.
| Section | Example content |
|---|---|
| Goals | Cut manual regression from 3 days to under 4 hours per release within 6 months. Keep feedback on every pull request under 15 minutes. Halve the number of production defects in invoicing and payments within 2 quarters. |
| Scope | In: invoicing, tax calculation, payment exports, user roles, public REST API, staging and QA environments. Out: legacy PDF report module (scheduled for replacement), admin back office, visual design checks. |
| Test levels | Unit tests owned by developers (target: all new business logic). API and integration tests owned by QA, covering invoicing and payment flows. UI tests limited to 15 - 20 critical end-to-end journeys. Performance tests for invoice generation and API under expected peak load. |
| Prioritization | First wave: tax and invoice calculation, bank payment export, permission checks. Second wave: reporting, notifications. Manual: onboarding redesign, exploratory sessions before each release. |
| Tools | xUnit for unit tests (.NET backend), API tests in C# alongside the backend code, Playwright for UI, k6 for load. Results published to the CI dashboard. |
| Test data | Synthetic companies and invoices generated per run; no production personal data; database reset after each suite. |
| Execution | Commit: unit tests (~3 min). Pull request: API and integration (~12 min). Pre-deploy to staging: smoke + critical regression, blocks release. Nightly: full regression, two browsers, load test weekly. |
| Ownership | Developers fix tests broken by their changes within one working day. QA lead owns the framework and flaky-test triage. |
| Metrics | Regression duration, defects found in production per release, flaky test rate (quarantine above a set threshold), pull request feedback time, hours spent on test maintenance per sprint. Reviewed monthly by QA lead and engineering manager. |
| Risks | UI changes in the planned redesign will break UI tests: keep UI layer thin. API version 2 migration in Q3: plan contract tests before it starts. |
| Review | After each quarterly planning, and whenever the release process changes. |
Treat this as a starting point, not a form to copy. The numbers will be different for your product, and some sections might need only two lines. What makes a successful test automation strategy is that every section has an answer someone agreed to.
Want a second pair of eyes on your strategy?
Send us your current setup or draft document. Our QA engineers will review it and suggest where to start.
Is Test Automation Worth It? How to Calculate ROI
The honest answer: usually, but not right away, and not always. Automation costs money up front, and the test suite is code that has to be maintained for as long as the product lives. The savings arrive later and depend mostly on how often the tests run.
A simple model is enough for a first estimate:
- Cost: hours to build the suite + hours per release to maintain it + manual testing you still do + infrastructure (CI runners, test environments, browser or device clouds).
- Saving: the manual effort on regression you no longer spend, in hours, multiplied by the number of releases.
Applied to the example project above, the numbers look like this. All of them are illustrative assumptions, so plug in your own.
| Metric | Manual only | With automation |
|---|---|---|
| Regression effort per release | 2 QA × 3 days = 48 hours | 20 hours of maintenance + 8 hours of remaining manual checks = 28 hours |
| Releases per year | 26 | 26 |
| Upfront investment | - | 600 hours to build the suite |
| Year 1 total | 1,248 hours | 600 + 728 = 1,328 hours |
| Year 2 total | 1,248 hours | 728 hours |
In this scenario, each release saves about 20 hours, so the 600-hour investment pays back after roughly 30 releases, about 14 months. In year one, the team actually spends slightly more time than before. From year two on, it saves around 520 hours a year. The table counts only people's time; infrastructure costs come on top and vary widely from one setup to another.
The 20 hours of maintenance per release is the assumption that moves this model the most, and it isn't an industry norm. On a stable product with a well-designed framework it can be much lower; on a product whose UI changes every sprint it can be higher. Measure it during your pilot rather than guessing.
The formula leaves out some of the most valuable effects. Developers get feedback in minutes instead of days, so bugs are fixed while the code is still fresh. Releases can happen more often, because regression no longer takes three days. And every defect caught before production avoids the much higher cost of fixing it after customers find it. These are harder to put in a spreadsheet, but they're often what convinces leadership once the first numbers are in.
Payback in Hours Is Not the Same as Financial ROI
Counting hours tells you when the effort pays back. Financial ROI needs money: (savings - costs) / costs. To get there, price each hour at the right rate. An hour of an automation engineer usually costs more than an hour of manual testing, so the same number of hours saved can be worth less than the hours model suggests. Add tool licenses, if you use paid tools, and infrastructure.
The benefits described above are real but harder to price. If the financial case only works once they're included, say so explicitly when you present it to leadership. A clearly labeled assumption is easier to defend than an optimistic number that falls apart in the first review.
Automation is unlikely to pay off when the product is short-lived, the UI changes completely every few weeks, releases happen a few times a year, or nobody will maintain the suite after the initial build. In those cases, a small smoke suite plus good manual testing may be the better investment.
Whichever way the math comes out, track the real numbers after launch. Regression time, maintenance hours, and production defects will tell you within a couple of quarters whether your estimate was right.
When you ask leadership for budget, lead with the cost and risk of today's manual bottleneck, then show payback with your own release cadence. Fund a first wave of high-risk tests plus a named owner - not an open-ended "automation program."
Starting Automation on an Existing Product with No Tests
Most advice assumes you're starting fresh. In reality, a lot of automation projects begin with a product that's been in production for years, has no automated tests worth mentioning, and maybe was built by a team that's no longer around. You can't stop development for six months to write tests, and you can't safely refactor without them.
The approach that works best here is to build protection from the outside in.
Start with a small smoke suite. Ten to twenty end-to-end checks on the flows that must never break: logging in, creating the core business object, paying, exporting. They're slow and somewhat brittle, but they give you a first warning system within weeks.
Add API tests around the riskiest modules. Look at where production bugs cluster and wrap those areas with API and integration tests. They're faster and more stable than UI tests, and they don't care if the front end is rewritten later.
Write characterization tests before you change anything. When the code is poorly understood, don't start by testing what it should do. Record what it does today, including the odd behavior, and lock it in. Then, when you refactor, any change in behavior shows up immediately and someone can decide whether it was intended.
Grow unit tests with every change. Make it a rule that new code and touched code get unit tests. Coverage climbs gradually from the parts of the system that actually change, which are also the parts most likely to break.
This order matters even more when automation is preparation for a bigger move, such as a cloud migration or modernizing a legacy application. Tests written before the migration are what let you prove that the new system behaves like the old one.
If your own team is fully occupied keeping the product running, it's common to add QA automation engineers to your team for this phase, so the safety net gets built without pausing feature work.
Need engineers to build and maintain your test suite? Our automation engineers can set up the framework, write the first waves of tests, and train your team to own them. Talk to our team about test automation
Best Practices That Keep Your Testing Process Maintainable
Building a test suite is the easy part. Keeping it useful two years later is where most of the effort goes, so these practices are about the long run.
Treat test code like production code
Test scripts live in version control next to the application, go through code review, and follow the same style rules. Use a structure that separates what a test checks from how it talks to the UI or API. The Page Object pattern is the classic example: when a page changes, you update one class instead of forty tests. A good test automation framework also makes two things easy: adding a new test, and understanding why an existing one failed.
Make UI tests hard to break
Most UI test failures come from fragile locators and timing. Prefer locators based on what the user sees: an element's role, its accessible name or label, its visible text. Modern frameworks such as Playwright recommend this approach, and it has a useful side effect: if a test can't find a button by its role and name, there's a good chance a screen reader can't either. For elements without a clear role or text, agree with developers on dedicated test attributes such as data-testid as a stable contract. Both options are far more robust than long CSS or XPath chains tied to page layout. Wait for specific conditions (an element is visible, a request has finished) rather than for fixed seconds. And keep the number of UI tests small; push checks down to the API or unit level whenever possible.
Deal with flaky tests immediately
A flaky test is worse than no test, because it teaches people to ignore failures. Set a rule: a test that fails intermittently goes into quarantine, out of the release-blocking suite, and gets an owner and a deadline. Then find the real cause. Shared test data, race conditions, and dependencies on other tests are the usual suspects. Automatic retries hide the problem; use them only as a short-term measure, and track how often they kick in.
Shift testing left, sensibly
Shift-left means catching problems earlier in the software development lifecycle. In practice, developers write unit and API tests as part of every change, QA engineers help design test scenarios while requirements are still being discussed, and the CI pipeline gives feedback on each pull request. It doesn't mean dumping all testing on developers, and it doesn't replace testing closer to release. It means fewer surprises arrive late.
Keep test data separate and disposable
Store test data outside the test logic, generate what you can, and make every test clean up after itself or run against a fresh dataset. Tests that depend on data left behind by other tests are a major source of flakiness and are painful to debug.
Build security checks into the pipeline
Automated tests aren't only about functionality. Dependency scanning, static analysis, and secrets detection can run in the same CI/CD pipeline as your functional tests and fail the build when something serious appears. Keep credentials for test environments out of test code, and give test environments their own access rules rather than reusing production ones.
Make results visible
A test run nobody looks at is wasted compute. Publish results where the team already works, show trends rather than single runs, and track a few health metrics for the suite itself: test execution time, flaky test rate, defects caught versus defects that escaped, and time spent on test maintenance. When maintenance starts outgrowing test creation, it's a signal to refactor before adding more.
How AI Changes Test Automation Strategy
AI tools are already useful in test automation, just not in the way the most ambitious marketing suggests.
What works well today: drafting test cases and test code from requirements or existing code, suggesting edge cases a human might skip, generating realistic synthetic test data, helping repair locators after UI changes, and summarizing why a batch of tests failed. Each of these speeds up test creation or maintenance, and a good engineer can review the output quickly.
What doesn't change: someone still has to decide what's worth testing, what "correct" means for your business, and whether a failing test is a bug or an outdated expectation. AI-generated tests can be confidently wrong, checking that the code does what it does rather than what it should. Every generated test needs the same review as one written by a person.
There's also a new reason to have a strategy. AI coding assistants let teams produce code much faster than before. If testing doesn't keep up, it becomes the bottleneck, or worse, changes ship with less verification than they used to. A clear strategy, with fast automated checks at the right levels, is what lets a team move faster without simply moving the risk to production.
In your strategy document, treat AI as a tool choice, not a separate plan. Note where you'll use it, who reviews its output, and how you'll measure whether it actually reduces effort.
Test Automation Strategy in Practice: Three Projects
Different products need different strategies. The three projects below had very different risks, and the strategy followed them.
A vCIO platform for a US consulting and coaching company
The client trains and equips managed service providers and was launching a new SaaS product for virtual CIO work. The business logic was complex, and a slow or buggy launch would cost customers. The strategy focused on functional regression and integration tests around the riskiest parts of the code, and developers received ready test sets for the riskiest parts of the code. Cross-browser testing covered Chrome and Firefox. The tooling included Selenium WebDriver with C#, Protractor, Jasmine, TypeScript, and Docker (Protractor has since reached end of life; Playwright or Cypress are the usual choices today).
Result: riskiest modules covered by automated regression and integration before launch; developers received ready test packs for high-risk code; Chrome and Firefox runs wired into the pipeline.
An EHR system integrated with health information exchange software
The client provides health information exchange solutions to hospitals, assisted living facilities, and pharmacies. The product combined several integrated modules and had to work reliably on web and mobile. The strategy combined compatibility testing across browsers and operating systems, performance testing against the agreed number of users, data transfer rate, and response time, and automated smoke tests for faster build verification. The tools included Cucumber and Apache JMeter.
Result: automated smoke on every build; compatibility covered across target browsers and OS; performance validated against agreed user load, data transfer rate, and response time.
Core estimation software for a global insurance company
The client insures logistics, energy, aviation, and engineering businesses worldwide. Its core estimation system had to run without disruption, and testing ran in parallel with development. Most checks were automated (functional, integration, and localization tests), while a small set stayed manual to give developers fast answers after hotfixes. At the end, the client received a reusable suite of automated tests to support future changes.
Result: most functional, integration, and localization checks automated in parallel with development; a reusable suite handed over for future releases; hotfixes still cleared through a small manual set for speed.
The Bottom Line
An effective test automation strategy matters more than the tool you pick. Decide what's worth automating, at which level, who owns it, and how you'll know it's working, and write it down where the team will see it. Start with a small, reliable suite around your riskiest flows, measure what it saves, and grow from there. A suite people trust beats a bigger one they ignore.